How to visualize any AI Model Architecture in Hugging Face
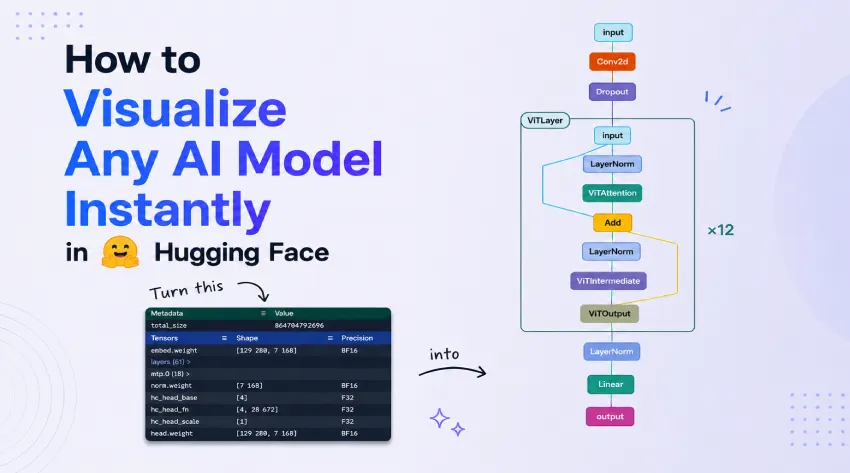
How to visualize any AI Model Architecture in Hugging Face

Understanding the modern architecture of AI harder than before. Open any Hugging Face repository and you’ll usually find large configuration files, layer definitions, parameter calculations, and descriptive model cards. what the model does but it rarely helps you understand How built in. That becomes a problem as many developers end up updating the architecture mentally … Read more
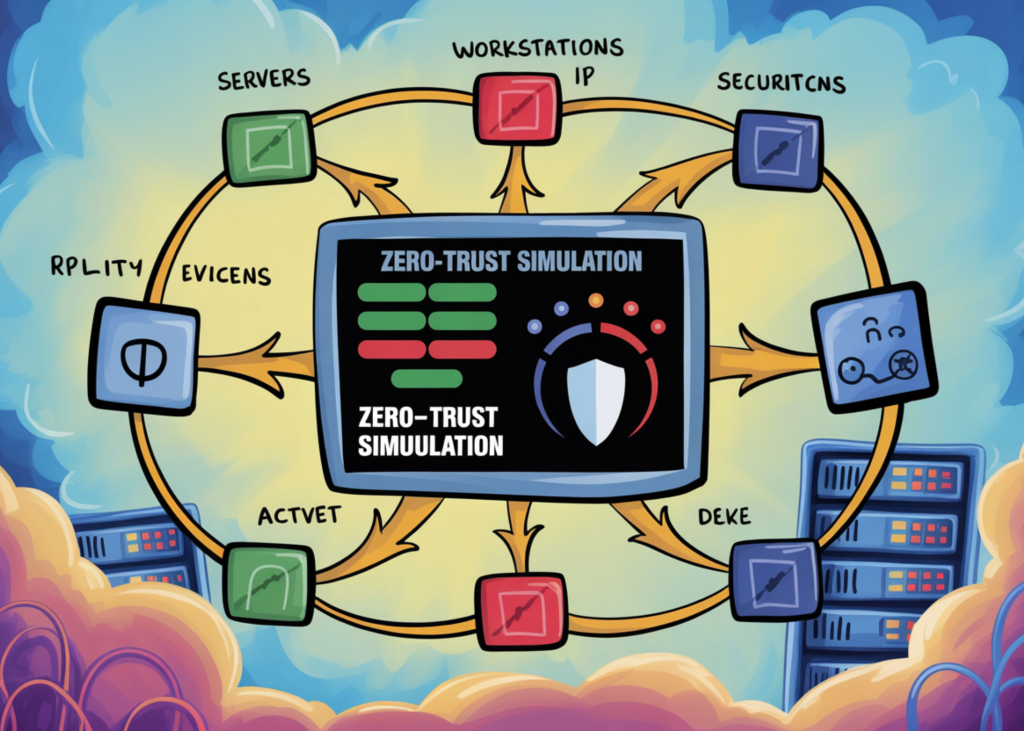
How to Build a Dynamic Zero-Trust Network Simulation with Graph-Based Micro-Segmentation, Adaptive Policy Engine, and Insider Threat Detection

How to Build a Dynamic Zero-Trust Network Simulation with Graph-Based Micro-Segmentation, Adaptive Policy Engine, and Insider Threat Detection

In this tutorial, we build a realistic Zero-Trust network simulation by modeling a sub-component environment as a directed graph and enforce every request to gain access through continuous authentication. We use a flexible policy engine that includes ABAC-style permissions and device orientation, MFA, path accessibility, location sensitivity, and live risk signals such as abnormal indicators … Read more

Google DeepMind Launches AI-Powered Mouse Pointer Powered by Gemini That Captures Visual and Semantic Content Around the Cursor

Google DeepMind Launches AI-Powered Mouse Pointer Powered by Gemini That Captures Visual and Semantic Content Around the Cursor

The mouse pointer has been at the heart of the personal computer for more than half a century. Tracks the cursor position. Registers clicks. Moreover, it does nothing. Google DeepMind researchers have revealed a set of test protocols and demos for the most advanced AI-powered pointer: one that understands not just where you’re pointing, but … Read more

Build a Hybrid-Memory Autonomous Agent with Modular Architecture and Tool Dispatch using OpenAI

Build a Hybrid-Memory Autonomous Agent with Modular Architecture and Tool Dispatch using OpenAI

class MemoryStoreTool(Tool): name = “memory_store” description = “Save an important fact or piece of information to long-term memory.” def __init__(self, memory: MemoryBackend): self._mem = memory def run(self, text: str, category: str = “general”) -> str: chunk_id = self._mem.store(text, {“category”: category}) return f”Stored as {chunk_id}.” def schema(self) -> Dict: return { “type”: “function”, “function”: { “name”: … Read more

Tilde Research Introduces Aurora: A Leverage-Aware Optimizer That Fixes the Hidden Neuron Death Problem in the Muon

Tilde Research Introduces Aurora: A Leverage-Aware Optimizer That Fixes the Hidden Neuron Death Problem in the Muon

Tilde Research researchers released Auroraa new optimizer for training neural networks that address the structural problem in the widely used Muon accelerator. The error silently kills a significant proportion of MLP neurons during training and keeps them dead forever. Aurora comes with 1.1B parameter pre-test, new state-of-the-art result in modded-nanoGPT speed benchmark, and unlocked codes. … Read more

An Introduction to Coding in Portfolio Development with skfolio for Building Tests, Tuning, and Comparing Modern Investment Strategies

An Introduction to Coding in Portfolio Development with skfolio for Building Tests, Tuning, and Comparing Modern Investment Strategies

factor_prices = load_factors_dataset() X_full, F_full = prices_to_returns(prices, factor_prices) X_tr, X_te, F_tr, F_te = train_test_split( X_full, F_full, test_size=0.33, shuffle=False ) fm = MeanRisk( objective_function=ObjectiveFunction.MAXIMIZE_RATIO, risk_measure=RiskMeasure.VARIANCE, prior_estimator=FactorModel(), ) fm.fit(X_tr, F_tr) ptf_fm = fm.predict(X_te); ptf_fm.name = “Factor Model” print(f”nFactor-model Sharpe: {ptf_fm.annualized_sharpe_ratio:.3f}”) pipe = Pipeline([ (“preselect”, SelectKExtremes(k=8, highest=True)), (“optimize”, MeanRisk( objective_function=ObjectiveFunction.MAXIMIZE_RATIO, risk_measure=RiskMeasure.VARIANCE)), ]) pipe.fit(X_train) ptf_pipe = pipe.predict(X_test); ptf_pipe.name = … Read more

Understanding LLM Distillation techniques – MarkTechPost

Understanding LLM Distillation techniques – MarkTechPost

Modern types of large languages ​​are no longer trained only on raw Internet text. Increasingly, companies are using powerful “teacher” models to help train smaller or more efficient “student” models. This process, widely known as LLM distillation or model to model traininghas become the primary method for building high-performance models at low computational cost. Meta … Read more

Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces Inference Memory Bandwidth by Over 50% Without Tokenization

Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces Inference Memory Bandwidth by Over 50% Without Tokenization

A team of researchers from Meta, Stanford University, and the University of Washington have introduced three new methods that greatly accelerate production in the Byte Latent Transformer (BLT) – a model of language structures that work directly on raw bytes instead of tokens. Byte-Level Models Are Slow to Understand To understand what this new research … Read more

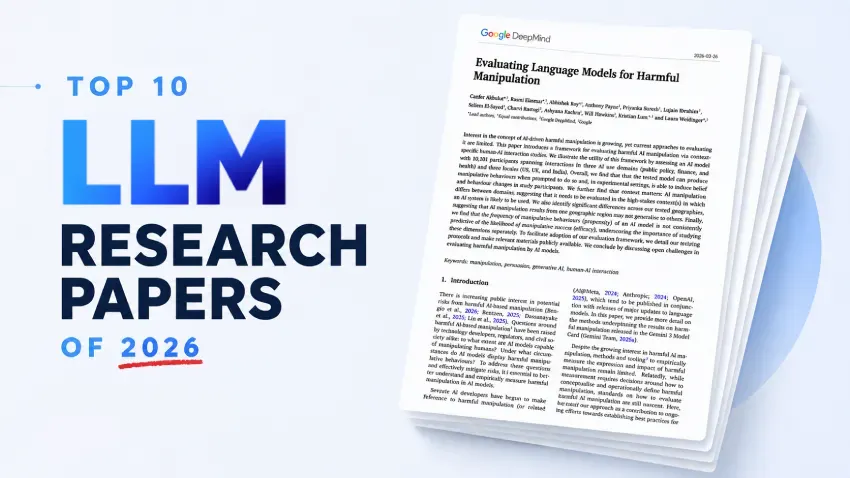
Top 10 LLM research papers of 2026

Top 10 LLM research papers of 2026

Large language models are no longer just scales. In 2026, the most important LLM research focuses on making models safer, more controllable, and more usable as real-world agents. From the risk of influence and approaches to harmful content to driving tools, temporal reasoning, and agent privacy, these papers show where LLM research is headed next. … Read more