Mistral AI Releases Voxtral TTS: An Open 4B Weighted Broadcast Speech Model for Low-Latency Multilingual Voice Generation
Mistral AI Releases Voxtral TTS: An Open 4B Weighted Broadcast Speech Model for Low-Latency Multilingual Voice Generation

Mistral AI released Voxtral TTSan open-source text-to-speech model that marks the company’s first major move into audio production. Following the release of its transcription models and language models, Mistral now provides the final ‘output layer’ of the audio stack, positioning itself as a direct competitor to proprietary voice APIs in the developer ecosystem. Voxtral TTS … Read more
NVIDIA AI Unveils ProRL Agent: A Decentralized Infrastructure-as-a-Service for Reinforcing Learning for Multi-Conversion LLM Agents at Scale

NVIDIA AI Unveils ProRL Agent: A Decentralized Infrastructure-as-a-Service for Reinforcing Learning for Multi-Conversion LLM Agents at Scale

Presented by NVIDIA researchers PRORL AGENTscalable infrastructure designed for reinforcement learning (RL) training for multi-turn LLM agents. By adopting a ‘Rollout-as-a-Service’ philosophy, the system separates the orchestration of agent rollout from the training loop. This architecture change addresses the inherent resource conflict between the intensive I/O environment and the GPU-intensive policy updates that currently hamper … Read more

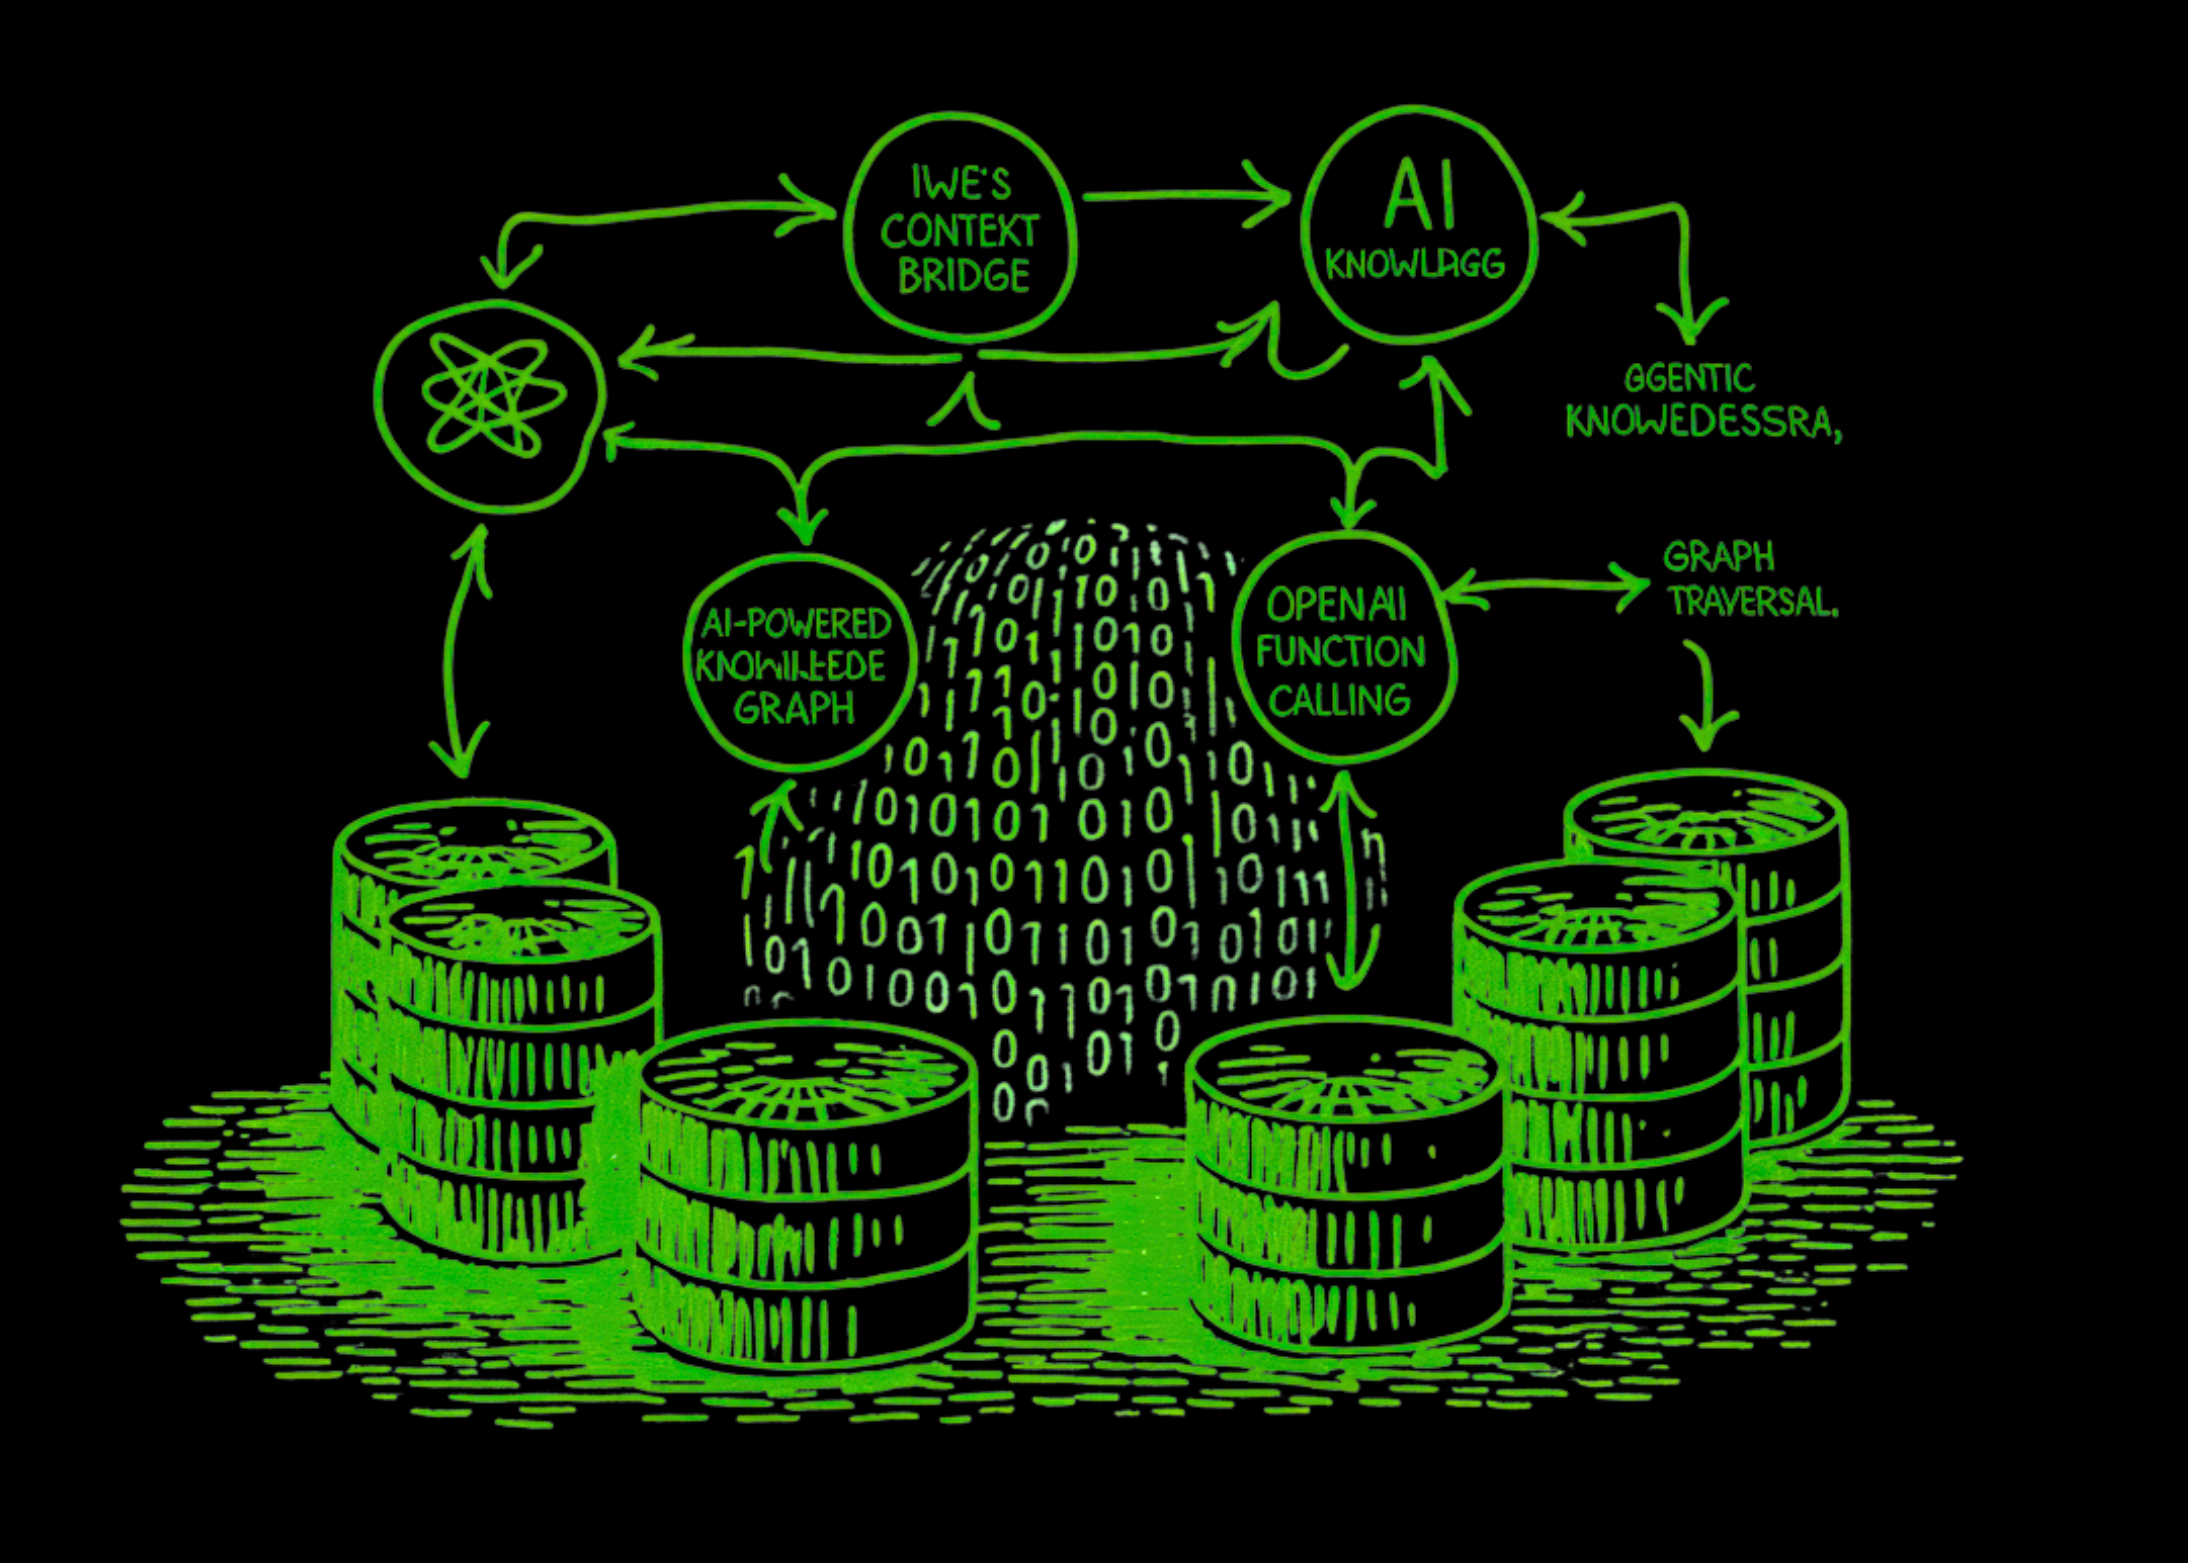
Implementation of IWE Content Bridge as an AI-Powered Knowledge Graph with Agentic RAG, OpenAI Function Calling, and Graph Traversal

Implementation of IWE Content Bridge as an AI-Powered Knowledge Graph with Agentic RAG, OpenAI Function Calling, and Graph Traversal

In this lesson, we use YOU: an open source, scalable personal information management system that manages put-down notes as a floating information graph. Since IWE is a CLI/LSP tool designed for local programmers. We build a virtual developer’s knowledge base from scratch, connect wiki links and markup links into a directed graph, and walk through … Read more

openJiuwen Community Releases ‘JiuwenClaw’: A Self Evolving AI Agent for Task Management

openJiuwen Community Releases ‘JiuwenClaw’: A Self Evolving AI Agent for Task Management

Over the past year, AI agents have evolved from answering questions to trying to perform real tasks. However, an important barrier has emerged: while many agents may seem smart during a conversation, they often ‘drop the ball’ when it comes to performing real-world tasks. Whether it’s an office workflow that breaks when needs change, or … Read more

Build an AI Assembly Summary with Claude Code + MCP

Build an AI Assembly Summary with Claude Code + MCP

Teams in all companies lose meeting notes and action items after discussions. This guide builds a permanent fix: Summary of the AI ​​Assembly and Task Scheduler using Claude Code and MCP. It processes the transcripts into organized summaries with tasks, decisions, and calendar reminders, connects to Google Calendar and Gmail, and stores everything in SQLite. … Read more

Meta Releases TRIBE v2: A Brain Coding Model That Predicts fMRI Responses to Across Video, Audio, and Text Stimuli

Meta Releases TRIBE v2: A Brain Coding Model That Predicts fMRI Responses to Across Video, Audio, and Text Stimuli

Neuroscience has long been a divide-and-conquer field. Researchers typically map specific cognitive functions to isolated brain regions—such as movement in area V5 or the surface of the fusiform gyrus—using models designed to summarize experimental paradigms. Although this has provided deep insight, the resulting field is fragmented, lacking a unified framework to explain how the human … Read more

Google Releases Gemini 3.1 Flash Live: A Multimodal Real-Time Voice Model for Low-Latency Audio, Video, and Instrumentation for AI Agents

Google Releases Gemini 3.1 Flash Live: A Multimodal Real-Time Voice Model for Low-Latency Audio, Video, and Instrumentation for AI Agents

Google has released Gemini 3.1 Flash Live in developer preview with the Gemini Live API in Google AI Studio. This model aims for lower latency, more natural, and reliable real-time voice interaction, serving as ‘Google’s highest quality audio and speech model to date.’ By processing multimodal streams in nature, the release provides a technical basis … Read more

Code Implementation of Qwen3.5 Refined Reasoning Models with Claude-Style Reasoning Using GGUF and 4-Bit Quantization

Code Implementation of Qwen3.5 Refined Reasoning Models with Claude-Style Reasoning Using GGUF and 4-Bit Quantization

In this tutorial, we work directly with Qwen3.5 models populated with Claude logic and set up a Colab pipeline that allows us to switch between the 27B GGUF variant and the lightweight 2B 4-bit version with one flag. We start by verifying the availability of the GPU, then conditionally install llama.cpp or transformers with bizandbytes, … Read more

Cohere AI Releases Cohere Transcribe: SOTA Automatic Speech Recognition (ASR) Model Powering Enterprise Speech Intelligence

Cohere AI Releases Cohere Transcribe: SOTA Automatic Speech Recognition (ASR) Model Powering Enterprise Speech Intelligence

In the case of enterprise AI, the bridge between unstructured audio and physical text is often a bottleneck of proprietary APIs and complex pipelines. Today, Cohere—a company generally known for its text generation and embedding models—has officially entered the Automatic Speech Recognition (ASR) market with the release of its latest model ‘.Cohere Transcribe‘. Architecture: Why … Read more