Tencent AI Open Sources Covo-Audio: 7B Speech Language Model and Suggestive Line for Real-Time Audio Conversations and Consultations
Tencent AI Open Sources Covo-Audio: 7B Speech Language Model and Suggestive Line for Real-Time Audio Conversations and Consultations

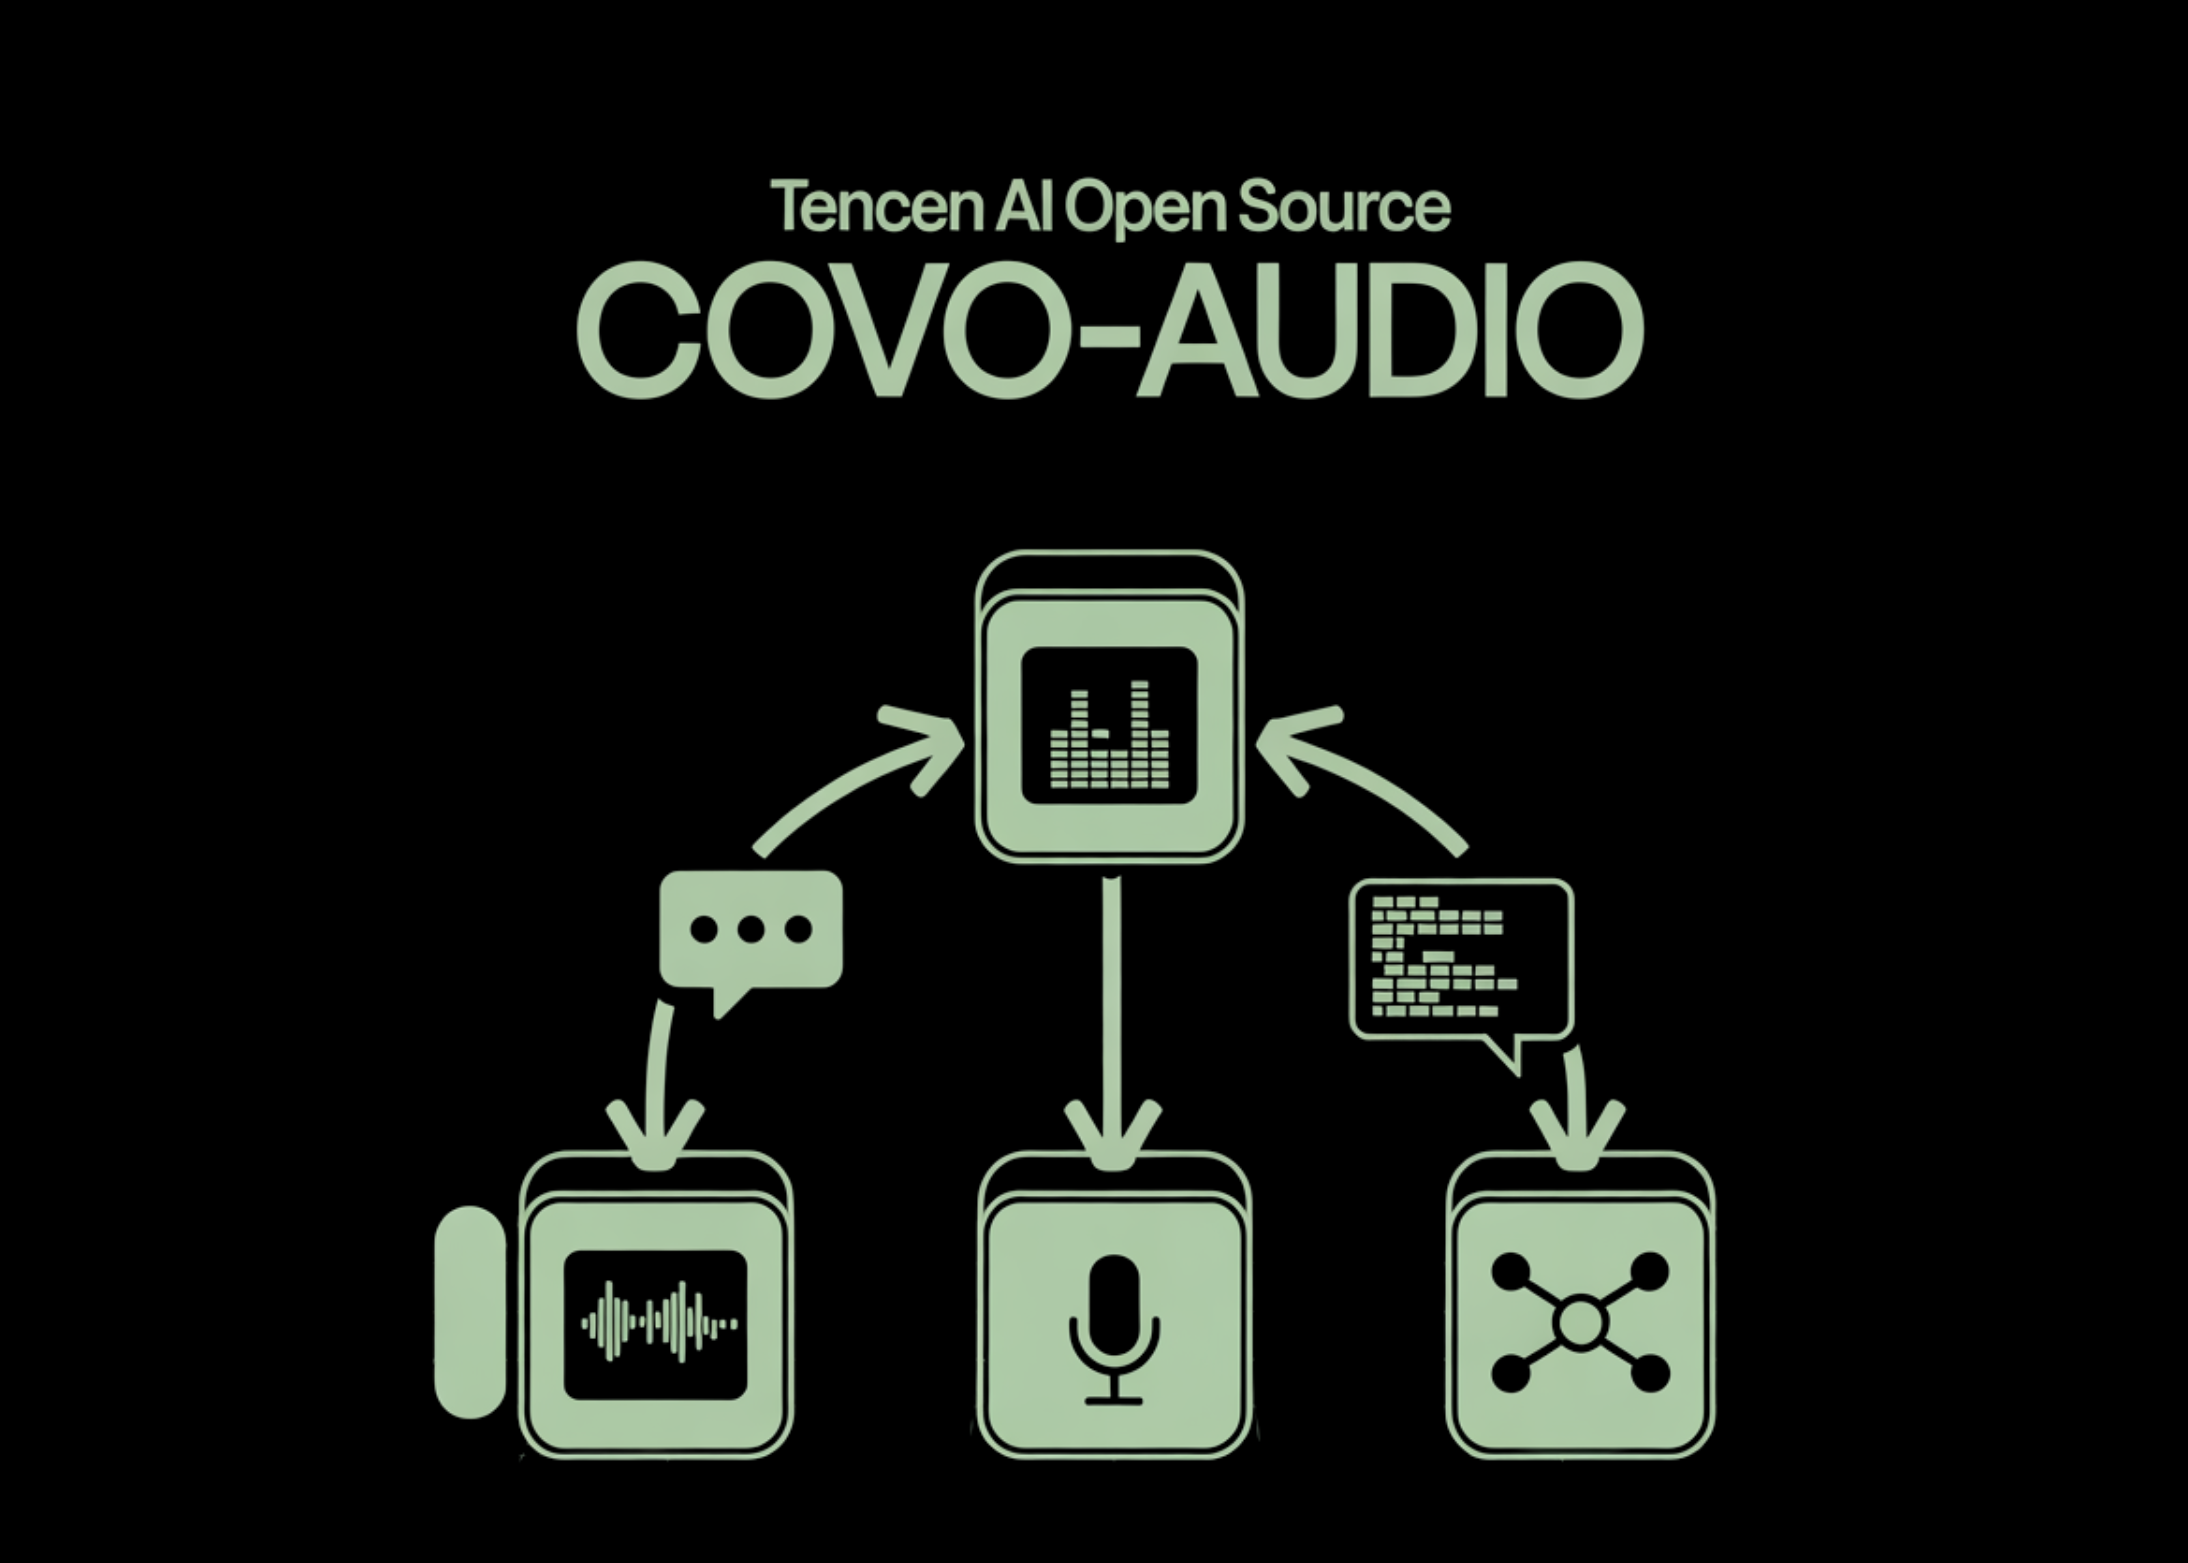
Tencent AI Lab has been released Covo-Audioparameter 7B-end-to-end Large Audio Language Model (LALM). The model is designed to integrate speech processing and language intelligence by directly processing continuous audio input and generating audio output within a single architecture. System Architecture The Covo-Audio framework consists of four main components designed for seamless cross-modal interoperability: Audio encoder: … Read more
How to Build a Vision-Driven Web Agent with MolmoWeb-4B Using Multimodal Reasoning and Action Prediction

How to Build a Vision-Driven Web Agent with MolmoWeb-4B Using Multimodal Reasoning and Action Prediction

def parse_click_coords(action_str): “”” Extract normalised (x, y) coordinates from a click action string. e.g., ‘click(0.45, 0.32)’ -> (0.45, 0.32) Returns None if the action is not a click. “”” match = re.search(r”click(s*([d.]+)s*,s*([d.]+)s*)”, action_str) if match: return float(match.group(1)), float(match.group(2)) return None def parse_action_details(action_str): “”” Parse a MolmoWeb action string into a structured dict. Returns: {“type”: “click”, … Read more

RIP OpenClaw? Meet Claude Dispatch

RIP OpenClaw? Meet Claude Dispatch

My biggest complaint with AI solutions is that they are too dependent on my presence in any activity. Even with agent AI now in the mix, complete automation of any complex process still seems like a myth. Tools like n8n and make.com require a lot of setup time and are not as efficient as traditional … Read more

NVIDIA AI Introduces PivotRL: A New AI Framework That Achieves Higher Agent Accuracy with 4x Fewer Outputs and More Efficient Turns

NVIDIA AI Introduces PivotRL: A New AI Framework That Achieves Higher Agent Accuracy with 4x Fewer Outputs and More Efficient Turns

After training Large-scale Language Modelers (LLMs) for long-horizon agent tasks—such as software engineering, web browsing, and the use of complex tools—they present a constant trade-off between computational efficiency and modeling in general.. Although Supervised Fine-Tuning (SFT) is computationally cheap, it often suffers from out-of-domain (OOD) performance degradation and struggles to generalize beyond its training distribution.. … Read more

Google Introduces TurboQuant: A New Compression Algorithm That Reduces LLM Key Value Cache Memory by 6x and Delivers Up to 8x Speedup, All with Zero Loss of Accuracy

Google Introduces TurboQuant: A New Compression Algorithm That Reduces LLM Key Value Cache Memory by 6x and Delivers Up to 8x Speedup, All with Zero Loss of Accuracy

The scaling of large-scale language models (LLMs) is increasingly constrained by the memory interface between High-Bandwidth Memory (HBM) and SRAM. In particular, the Key-Value (KV) cache scales with model size and context length, creating a significant bottleneck for long content interpretation. Google’s research team made a proposal TurboQuanta data-insensitive estimation framework designed to achieve very … Read more

Paged Attention to Major Language Models LLMs

Paged Attention to Major Language Models LLMs

When using LLMs at scale, the real limitation is GPU memory rather than computation, mainly because each application needs a KV cache to store token-level data. In a typical setup, a large fixed memory block is reserved for each request based on the maximum sequence length, resulting in significant unused space and consistency limits. Paged … Read more

This AI Paper Introduces TinyLoRA, a 13-Parameter Fine-Tuning Method That Achieves 91.8 Percent of GSM8K on Qwen2.5-7B

This AI Paper Introduces TinyLoRA, a 13-Parameter Fine-Tuning Method That Achieves 91.8 Percent of GSM8K on Qwen2.5-7B

Researchers from FAIR on the Meta, Cornell Universityagain Carnegie Mellon University showed that large-scale linguistic models (LLMs) can learn reasoning using a remarkably small number of trained parameters. The research team presents TinyLoRAa parameter that can be down to a single parameter that can be trained under extreme sharing settings. Applying this method to a … Read more

Yann LeCun’s New LeWorldModel (LeWM) Guides Research JEPA Collapse in Pixel-based Predictive World Modeling

Yann LeCun’s New LeWorldModel (LeWM) Guides Research JEPA Collapse in Pixel-based Predictive World Modeling

World Models (WMs) are a central framework for developing agents that think and plan in a discrete collective environment. However, training these models directly from pixel data often leads to ‘representation collapse,’ where the model generates unwanted embeddings to partially satisfy the prediction objectives. Current methods try to avoid this by relying on sophisticated heuristics: … Read more

New Meta AI Hyperagents Don’t Just Solve Tasks—They Rewrite the Rules of How They Learn

New Meta AI Hyperagents Don’t Just Solve Tasks—They Rewrite the Rules of How They Learn

The dream of iterative self-improvement in AI—where the system doesn’t just get better at the job, but gets better reading-It has long been the ‘holy land’ of the field. While theoretical models such as Filling Machine have been around for decades, they have remained largely ineffective in real-world settings. That changed with Darwin Gödel Machine … Read more